
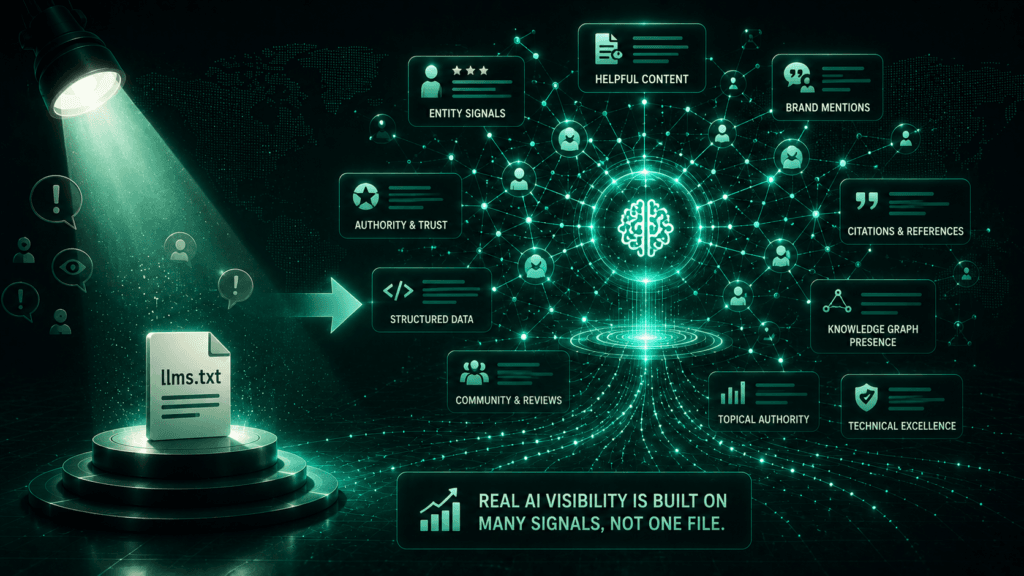
The search marketing industry has a long history of seeking out quick-fix configuration files to bypass technical optimization. In generative search, the latest trend is the /llms.txt file—a proposed Markdown manifest hosted at a website’s root domain intended to feed large language models a curated summary of key URLs.
Core Definition: llms.txt is a proposed standard designed to provide developer agents and contextual LLMs with a plain-text Markdown summary of a website’s key documentation and resources. It is not an official ranking signal for Google AI Overviews, Perplexity, or SearchGPT.
Believing that dropping a 5KB text file on your server will suddenly unlock thousands of AI citations is fundamentally mistaken. Retrieval-Augmented Generation (RAG) engines crawl, chunk, and cite websites using decentralized algorithmic models—not manual text shortcuts.
The Reality of How AI Engines Index Content
When tools like ChatGPT, Perplexity, or Google AI Overviews answer complex prompts, their retrieval pipelines do not stop to read an /llms.txt wish list. Instead, they execute real-time fan-out queries directly across the open web.
| Stage in Retrieval Pipeline | Traditional Google Search | AI Search Engines (RAG) |
| User Query / Input | Searches fragmented keywords or exact phrases. | Inputs natural conversational prompts or complex tasks. |
| Retrieval Model | Crawlers match keyword density and domain metrics. | Sub-query fan-out parses multiple sources simultaneously. |
| Data Sources Ingested | First-party static HTML and meta tags. | First-party pages + objective UGC (Reddit, Quora, reviews). |
| Validation Layer | Algorithmic PageRank and backlink volume. | Cross-entity consensus, sentiment, and fact density. |
| Final Output | Ranked list of 10 blue links requiring manual clicks. | Synthesized direct answer with inline source citations. |
Language models evaluate your authority based on content chunking, verified factual density, and off-page consensus. Relying on an /llms.txt file while neglecting structural content architecture is equivalent to expecting an XML sitemap to automatically rank low-quality content on Google’s first page.
What llms.txt Does vs. What Drives AI Search Visibility
Understanding where to allocate development resources requires separating developer agent tooling from organic AI search optimization.
| Feature / Signal | The llms.txt File | What Actually Drives AI Citations |
| Primary Consumer | Context-window dev tools & autonomous coding agents | Live search RAG pipelines (OAI-SearchBot, PerplexityBot) |
| Search Engine Support | Ignored by Google Search systems; treated as auxiliary | Fully integrated into Google, Perplexity, and OpenAI indexing |
| Authority Weight | Zero direct ranking or citation weight | High: Driven by semantic triples, schema, and domain trust |
| Technical Core | Flat Markdown link list with brief notes | Clean semantic HTML, server-side rendering, and JSON-LD |
To understand how modern search bots access your site infrastructure, review our technical guide on How to Audit and Unblock AI Web Crawlers.
4 Real Drivers of AI Search Visibility
Instead of banking on file shortcuts, generative visibility requires engineering authority directly into your content assets.
[ Inverted Pyramid Answers ] ➔ [ Structural Entity Triples ] ➔ [ Off-Page Third-Party Signals ] ➔ [ Clean Server-Side Rendering ]
1. Inverted-Pyramid Information Architecture
AI models parse content in discrete semantic chunks rather than reading full pages chronologically.
- State a direct, 40-to-60-word answer immediately beneath each H2 or H3 heading before providing background details.
- Format complex workflows into structured bulleted lists or comparison tables, which deliver a 30% to 40% lift in AI citation probability.
2. Explicit JSON-LD Schema & Entity Triples
Do not leave your brand’s relationships open to algorithmic interpretation. Implement comprehensive JSON-LD schema (such as FAQPage, Article, or Organization) containing explicit about and mentions entity associations.
- Map your brand capabilities into explicit semantic triples (e.g., [Content Spring] → [Offers] → [GEO & AEO Services]).
- Ensure your entity architecture is validated using our Entity-First SEO & Google Knowledge Graph Guide.
3. Off-Page Consensus & UGC Sentiment
RAG retrieval engines evaluate third-party consensus to prevent commercial bias and hallucination. Positive, unlinked brand citations across Reddit, Quora, and review directories provide the statistical validation LLMs require to cite you as a trusted source.
- Discover how external discussions fuel search models in our playbook on Community-Led GEO.
4. Direct Server-Side Rendering & Firewall Health
If an AI retrieval bot hits a JavaScript execution barrier or a CDN challenge screen, it immediately bypasses your page. Ensure core informational text and data nodes are served directly in clean, server-side rendered HTML.
To evaluate your site’s complete readiness, run through our full GEO Audit Checklist.
🛠️ Summary Action Item: Real AI Visibility Rollout
To build lasting generative engine visibility, execute this technical workflow:
- Audit Top-Traffic Landing Pages: Rewrite introductory sections of your top 10 informational pages to ensure the first 200 words are concise, factual, and declare the exact technical purpose of the asset.
- Standardize Structured Schema: Embed machine-readable JSON-LD schema across your core service hubs and cross-link them with your foundational articles using our Answer Engine Optimization Strategy.
- Isolate AI Referrals in Analytics: Verify downstream impact by monitoring generative citations and isolating ChatGPT and Perplexity referrals using our guide on How to Measure AI Search Traffic in GA4 & Search Console.
Frequently Asked Questions (FAQs)
Does having an llms.txt file hurt my website?
No. An llms.txt file is harmless, lightweight, and can be useful for developer agents querying documentation sites. However, treating it as a substitute for structured on-page GEO and entity optimization will yield zero search gains.
Does Google AI Overviews use llms.txt?
No. Google’s Search documentation explicitly states that Google systems do not use llms.txt files to determine rankings or source inclusion for AI Overviews or AI Mode. Google generates its AI summaries from its standard core search index.
Why do AI engines skip some website content?
AI crawlers operate under strict token and latency budgets. If content is locked behind heavy client-side JavaScript, unlabelled tables, or multi-paragraph narrative introductions, the retrieval engine will favor a competitors’ clean, structured data block instead.
What is the most important factor for getting cited by ChatGPT?
ChatGPT’s search retrieval engine prioritizes clear semantic structure, authoritative third-party entity mentions, and concise, factual answer blocks. For deep algorithmic details, see our analysis on How ChatGPT Chooses Which Brands to Recommend.
Would you like to draft Topic 4 (Capturing Commercial Intent in AI Overviews: How to Optimize High-Converting Product & Service Pages) next, or should we generate an AI image prompt for this article’s thumbnail?