
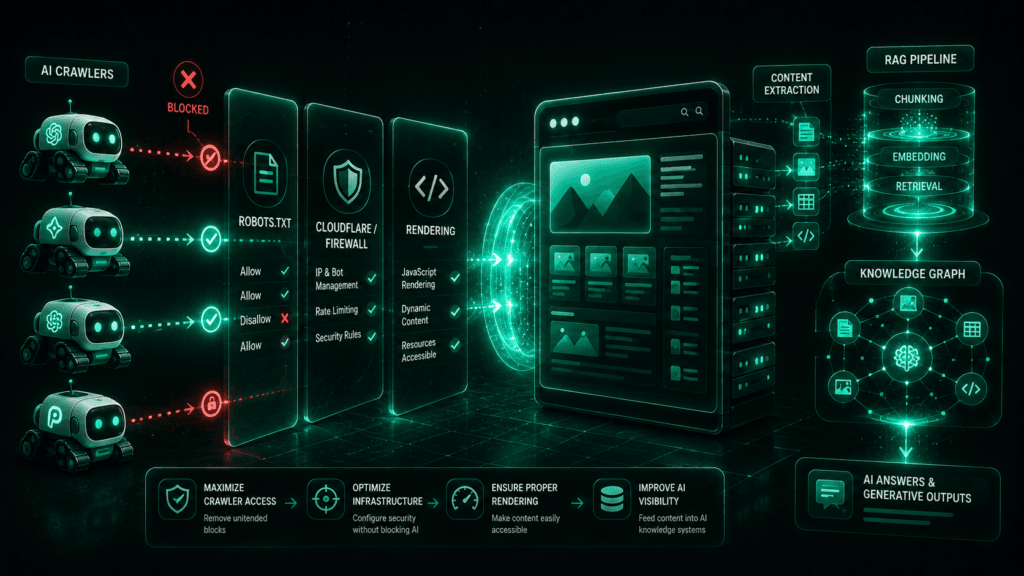
Maintaining standard organic Google rankings is no longer a guarantee of digital brand visibility. Across modern generative ecosystems, large language models (LLMs) such as ChatGPT, Perplexity, Claude, and Google Gemini ingest web data through specialized Retrieval-Augmented Generation (RAG) crawlers.
Core Definition: AI Crawler Optimization is the technical practice of configuring server-side directives (robots.txt), Web Application Firewalls (WAFs), and rendering pipelines so autonomous retrieval bots (e.g., OAI-SearchBot, PerplexityBot) can crawl, parse, and cite your structured content in real-time generative summaries without triggering automated firewall blocks.
Millions of websites experience sudden, unexplained drops in AI citations despite holding first-page Google rankings. In most cases, this is caused by silent server-level barriers: default CDN security toggles, restrictive directives, or client-side JavaScript rendering issues that render pages unreadable to retrieval engines.
Why Traditional Crawler Access Is No Longer Enough
Classical search engine indexing is asynchronous: Googlebot visits a page, stores the HTML, renders JavaScript over time, and updates a centralized index. In contrast, generative search engines operate on synchronous, on-demand retrieval loops.
[ User Prompts Answer Engine ]
│
▼
[ Real-Time RAG Trigger ] ───► Fetches Live URLs via Search Bots
│
┌────────┴────────┐
▼ ▼
[ 200 OK HTML ] [ 403 Forbidden / JS Block ]
│ │
▼ ▼
[ AI Citation ] [ Excluded from Answer ]
When an engine like SearchGPT or Perplexity evaluates an answer, it deploys live bots (such as OAI-SearchBot or PerplexityBot) to pull exact page snippets. If your server returns a 403 Forbidden status code or forces a CAPTCHA verification challenge, the model bypasses your URL within milliseconds and cites a competitor instead.
3 Pillars of an AI Crawler Technical Audit
Securing full accessibility for retrieval models requires auditing three layers of your technical infrastructure: directives, firewalls, and rendering pipelines.
[ robots.txt Directives ] ➔ [ CDN & WAF Configuration ] ➔ [ Server-Side RAG Rendering ]
1. Configure Explicit robots.txt Permissions
Differentiate between bots that train offline foundational models and bots that retrieve real-time data for search citations. If you want your site cited in live search results, ensure search-specific user agents are granted access.
A modern, citation-friendly robots.txt snippet should explicitly include:
Plaintext
# Allow Real-Time Search & Retrieval Crawlers
User-agent: OAI-SearchBot
Allow: /
User-agent: PerplexityBot
Allow: /
User-agent: ClaudeBot
Allow: /
User-agent: Bingbot
Allow: /
# Disallow Private Directories
Disallow: /wp-admin/
Disallow: /checkout/
To align your crawler permissions with comprehensive answer extraction, ensure you have implemented our core Answer Engine Optimization Strategy.
2. Adjust Cloudflare and WAF “AI Bot” Blocks
Many Content Delivery Networks (CDNs)—including Cloudflare, Fastly, and AWS CloudFront—introduced automated one-click toggles designed to block AI scrapers.
- The Problem: Enabling generic “Block AI Scrapers and Crawlers” features in Cloudflare often blocks search retrieval bots alongside unvetted model scrapers.
- The Solution: Navigate to Security $\rightarrow$ Bots inside Cloudflare. Ensure that verified search bots are whitelisted. Create Custom WAF skip rules for verified User-Agents matching OAI-SearchBot and PerplexityBot.
3. Ensure Clean Server-Side RAG Rendering
Retrieval engines prioritize fast text ingestion over heavy DOM rendering. If key specifications, pricing details, or core data are rendered exclusively through client-side JavaScript (CSR) or hidden inside dynamic accordions, headless AI bots will fail to parse the content.
- Serve pure HTML containing your primary content nodes directly from the initial payload.
- Structure key answers in clean markdown tables and structured lists to accelerate machine parsing.
For a broader evaluation of on-page indexing health, review our complete GEO Audit Checklist.
AI Crawlers Reference Cheat Sheet
| Crawler / User-Agent | Parent Platform | Primary Function | Recommended Action |
| OAI-SearchBot | OpenAI (SearchGPT / ChatGPT) | Real-time search retrieval & citation | Allow (Required for ChatGPT links) |
| GPTBot | OpenAI | Foundational model training data collection | Optional (Allow or Disallow based on policy) |
| PerplexityBot | Perplexity AI | Real-time indexation & source validation | Allow (Required for Perplexity citations) |
| ClaudeBot | Anthropic Claude | Search ingestion & model evaluation | Allow (Ensures citation across Claude) |
| Google-Extended | Google Gemini | Gemini model training control | Optional (Does not affect standard Googlebot) |
To understand how machine permissions interact with machine-readable entities, check out our guide on Entity-First SEO & Google Knowledge Graph.
🛠️ Summary Action Item: 30-Day AI Accessibility Protocol
To verify that your site is fully accessible to AI retrieval engines, complete this rollout plan:
- Conduct Server Log Audits: Filter your access logs for OAI-SearchBot and PerplexityBot. Confirm that responses return 200 OK status codes and identify any 403 or 429 errors.
- Review Firewall Exceptions: Audit your CDN/WAF rules to verify that automated anti-bot protections are not intercepting verified generative search crawlers.
- Validate Referral Attribution: Track incoming search bot traffic and measure resulting user sessions using custom regex filters from our blueprint on How to Measure AI Search Traffic in GA4 & Search Console.
Frequently Asked Questions (FAQs)
What happens if I block GPTBot in robots.txt?
Blocking GPTBot prevents OpenAI from using your website data to train future foundational models. However, to ensure your site can still appear in real-time ChatGPT search responses, you should keep OAI-SearchBot allowed.
Does Cloudflare automatically block AI search citations?
If Cloudflare’s “Block AI Scrapers” or strict Managed Bot Challenge settings are enabled globally without custom exceptions, the firewall may block real-time RAG bots like PerplexityBot, preventing your pages from being cited in generative answers.
Can AI search engines render client-side JavaScript?
While some bots possess basic headless rendering capabilities, RAG retrieval cycles operate on tight execution time limits. Content rendered purely via heavy client-side JavaScript risks being skipped in favor of static, server-rendered HTML.
How do I check if my pages are blocked by AI bots?
You can check access by inspecting web server and CDN access logs for the specific User-Agent strings of AI crawlers. For step-by-step visibility tracking frameworks, see our guide on How to Track AI Search Visibility & KPIs